
Datasets:


Create README.md with duckDB and hf datasets examples
Browse files
README.md
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
task_categories:
|
| 3 |
+
- text-generation
|
| 4 |
+
pretty_name: Common Crawl Host Index v2
|
| 5 |
+
size_categories:
|
| 6 |
+
- 10B<n<100B
|
| 7 |
+
---
|
| 8 |
+
|
| 9 |
+
# Common Crawl Host Index v2
|
| 10 |
+
|
| 11 |
+
GitHub: https://github.com/commoncrawl/cc-host-index
|
| 12 |
+
|
| 13 |
+
Each crawl, we generate a Host Index, which aggregates information about each web hosted visited during the crawl. The
|
| 14 |
+
information is aggregated from the Common Crawl [columnar index](https://commoncrawl.org/blog/index-to-warc-files-and-urls-in-columnar-format),
|
| 15 |
+
[web graph](https://commoncrawl.org/web-graphs), and [raw crawler logs](https://data.commoncrawl.org).
|
| 16 |
+
|
| 17 |
+
## Quickstart
|
| 18 |
+
|
| 19 |
+
### Using duckdb:
|
| 20 |
+
|
| 21 |
+
DuckDB can [read directly from Huggingface](https://huggingface.co/docs/hub/en/datasets-duckdb):
|
| 22 |
+
|
| 23 |
+
```sql
|
| 24 |
+
$ duckdb
|
| 25 |
+
D FROM 'hf://datasets/commoncrawl/host-index-testing-v2/data/crawl=CC-MAIN-2025-18/*.parquet' LIMIT 3;
|
| 26 |
+
┌─────────────────────┬─────────────┬────────────────┬────────────┬────────────────┬───┬───────────────────┬─────────────────┬───────────┬───────────────────┬─────────────────┐
|
| 27 |
+
│ nutch_unfetched_pct │ fetch_other │ fetch_200_lote │ nutch_gone │ nutch_gone_pct │ … │ fetch_notModified │ nutch_redirPerm │ fetch_200 │ nutch_notModified │ crawl │
|
| 28 |
+
│ int8 │ int64 │ int64 │ int64 │ int8 │ │ int64 │ int64 │ int64 │ int64 │ varchar │
|
| 29 |
+
├─────────────────────┼─────────────┼────────────────┼────────────┼────────────────┼───┼───────────────────┼─────────────────┼───────────┼───────────────────┼─────────────────┤
|
| 30 |
+
│ 0 │ 0 │ 0 │ 3 │ 7 │ … │ 0 │ 0 │ 18 │ 0 │ CC-MAIN-2025-18 │
|
| 31 |
+
│ 6 │ 0 │ 8 │ 0 │ 0 │ … │ 0 │ 0 │ 10 │ 41 │ CC-MAIN-2025-18 │
|
| 32 |
+
│ 80 │ 0 │ 0 │ 8 │ 17 │ … │ 0 │ 0 │ 0 │ 0 │ CC-MAIN-2025-18 │
|
| 33 |
+
├─────────────────────┴─────────────┴────────────────┴────────────┴────────────────┴───┴───────────────────┴─────────────────┴───────────┴───────────────────┴─────────────────┤
|
| 34 |
+
│ 3 rows 43 columns (10 shown) │
|
| 35 |
+
└──────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────┘
|
| 36 |
+
D SELECT surt_host_name FROM 'hf://datasets/commoncrawl/host-index-testing-v2/data/crawl=CC-MAIN-2025-18/*.parquet' LIMIT 3;
|
| 37 |
+
┌──────────────────────┐
|
| 38 |
+
│ surt_host_name │
|
| 39 |
+
│ varchar │
|
| 40 |
+
├──────────────────────┤
|
| 41 |
+
│ ae,ebury │
|
| 42 |
+
│ be,echappeeduhainaut │
|
| 43 |
+
│ au,com,echolaw │
|
| 44 |
+
└──────────────────────┘
|
| 45 |
+
```
|
| 46 |
+
|
| 47 |
+
### Using Hugging Face `datasets` library:
|
| 48 |
+
|
| 49 |
+
"Streaming" mode (`streaming=True`) is recommended (see [the `datasets` docs](https://huggingface.co/docs/datasets/v4.4.1/en/stream)). This avoids the need to download all of the parquet files up-front.
|
| 50 |
+
|
| 51 |
+
```python
|
| 52 |
+
>>> from datasets import load_dataset
|
| 53 |
+
>>> ds = load_dataset("commoncrawl/host-index-testing-v2", data_dir="data/crawl=CC-MAIN-2025-18", split="train", streaming=True)
|
| 54 |
+
Resolving data files: 100%|████████████| 30/30 [00:00<00:00, 43614.95it/s]
|
| 55 |
+
>>> print(next(iter(ds)))
|
| 56 |
+
{'nutch_unfetched_pct': 0, 'fetch_other': 0, 'fetch_200_lote': 0, 'nutch_gone': 3, 'nutch_gone_pct': 7, 'robots_gone': 0, 'robots_5xx': 0, 'hcrank10': 3.446, 'warc_record_length_median': 32867, 'hcrank': 11908759.0, 'nutch_fetched': 42, 'nutch_notModified_pct': 0, 'robots_4xx': 0, 'nutch_redirTemp': 0, 'fetch_redirPerm': 2, 'fetch_4xx': 0, 'url_host_tld': 'ae', 'nutch_fetched_pct': 93, 'robots_notModified': 0, 'robots_other': 0, 'nutch_redirTemp_pct': 0, 'fetch_200_lote_pct': 0, 'nutch_numRecords': 45, 'robots_3xx': 0, 'robots_redirTemp': 0, 'warc_record_length_av': 31769, 'url_host_registered_domain': 'ebury.ae', 'surt_host_name': 'ae,ebury', 'nutch_redirPerm_pct': 0, 'fetch_redirTemp': 0, 'robots_200': 3, 'fetch_3xx': 0, 'fetch_5xx': 0, 'nutch_unfetched': 0, 'prank': 4.73550733982247e-09, 'fetch_gone': 0, 'prank10': 0.0, 'robots_redirPerm': 1, 'fetch_notModified': 0, 'nutch_redirPerm': 0, 'fetch_200': 18, 'nutch_notModified': 0}
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
## Use Cases
|
| 60 |
+
|
| 61 |
+
### Example questions this index can answer
|
| 62 |
+
|
| 63 |
+
- What's our history of crawling a particular website, or group of websites?
|
| 64 |
+
- What popular websites have a lot of non-English content?
|
| 65 |
+
- What popular websites seem to have so little content that we might need to execute javascript to crawl them?
|
| 66 |
+
|
| 67 |
+
### Example questions that we'll use to improve our crawl
|
| 68 |
+
|
| 69 |
+
- What's the full list of websites where more than half of the webpages are primarily not English?
|
| 70 |
+
- What popular websites end our crawls with most of their crawl budget left uncrawled?
|
| 71 |
+
|
| 72 |
+
### Example questions that future versions of this host index can answer
|
| 73 |
+
|
| 74 |
+
- What websites have a lot of content in particular languages?
|
| 75 |
+
- What websites have a lot of content with particular Unicode scripts?
|
| 76 |
+
|
| 77 |
+
## Examples
|
| 78 |
+
|
| 79 |
+
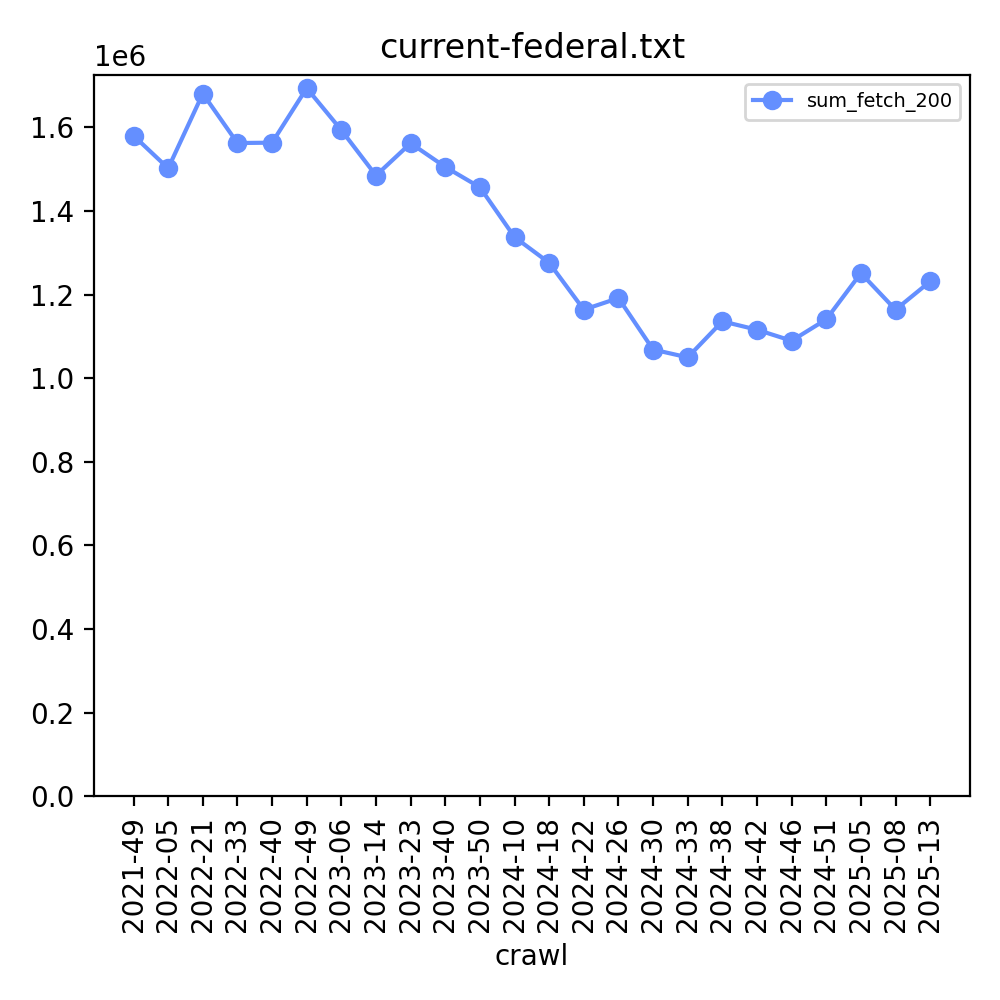
US Federal government websites in the *.gov domain (about 1,400 domains, y-axis scale is millions):
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
[See all graphs from this dataset](https://commoncrawl.github.io/cc-host-index-media/current-federal.txt.html)
|
| 84 |
+
|
| 85 |
+
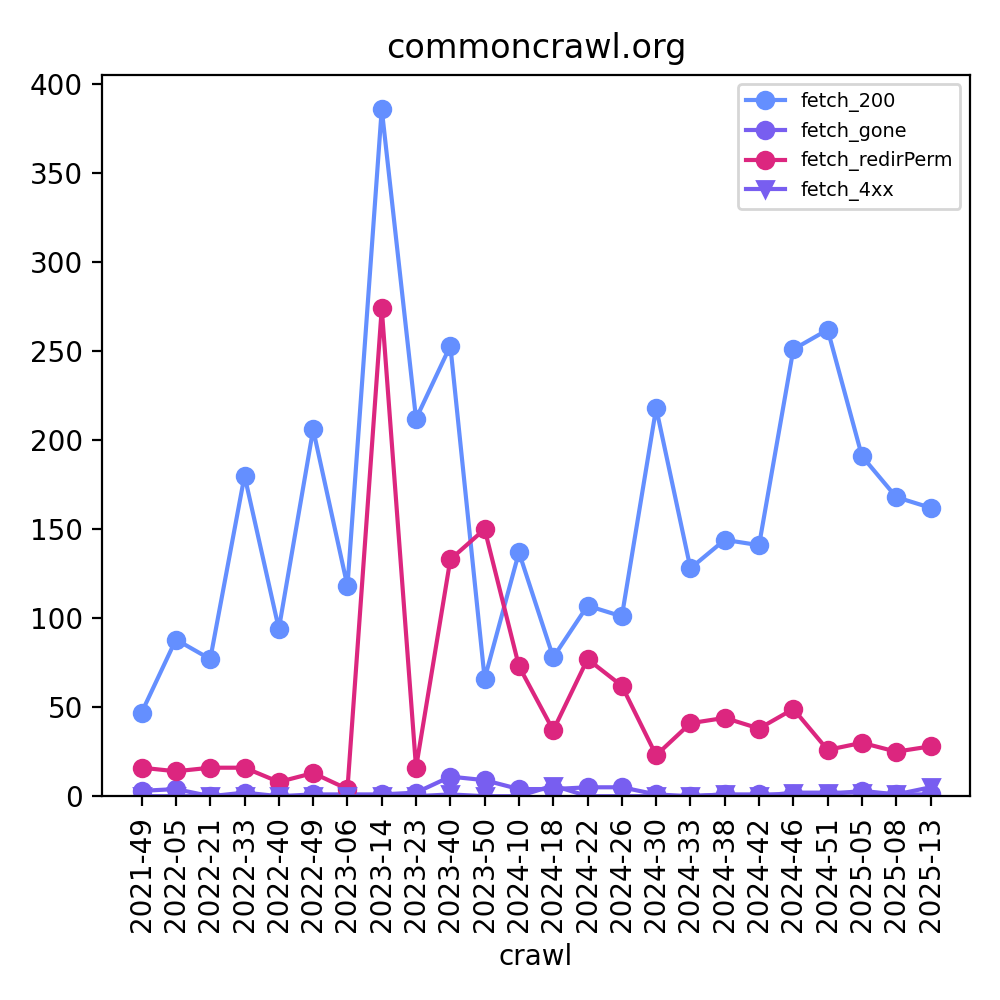
commoncrawl.org fetch. You can see that we revamped our website in CC-2023-14, which caused a lot of
|
| 86 |
+
permanent redirects to be crawled in the next few crawls:
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
[See all graphs from this dataset](https://commoncrawl.github.io/cc-host-index-media/commoncrawl.org.html)
|
| 91 |
+
|
| 92 |
+
### Python code examples
|
| 93 |
+
|
| 94 |
+
More examples of how to use this dataset with Python can be found at the [Common Crawl Host Index GitHub repo](https://github.com/commoncrawl/cc-host-index).
|
| 95 |
+
|
| 96 |
+
## Highlights of the Schema
|
| 97 |
+
|
| 98 |
+
- There is a Hive-style partition on `crawl`, which is a crawl name like `CC-MAIN-2025-13`.
|
| 99 |
+
- There is one row for every webhost in the web graph, even if we didn't crawl that website in that particular crawl
|
| 100 |
+
- The primary key is `surt_host_name`, which stores the URL in [Sort-friendly URI Reordering Transform (SURT) format](http://crawler.archive.org/articles/user_manual/glossary.html#surt). For example, the URI `commoncrawl.org` -> becomes `org,commoncrawl)`.
|
| 101 |
+
- There is also `url_host_tld`, which we recommend that you use whenever possible (eg `org` for commoncrawl.org) - it typically improves performance, significantly.
|
| 102 |
+
- There are counts of what we stored in our archive (`warc`, `crawldiagnostics`, `robots`)
|
| 103 |
+
- `fetch_200, fetch_3xx, fetch_4xx, fetch_5xx, fetch_gone, fetch_notModified, fetch_other, fetch_redirPerm, fetch_redirTemp`
|
| 104 |
+
- `robots_200, robots_3xx, robots_4xx, robots_5xx, robots_gone, robots_notModified, robots_other, robots_redirPerm, robots_redirTemp`
|
| 105 |
+
- There is ranking information from the [web graph](https://commoncrawl.org/web-graphs): harmonic centrality, page rank, and both normalized to a 0-10 scale
|
| 106 |
+
- `hcrank`, `prank`, `hcrank10`, `prank10`
|
| 107 |
+
- There is a language summary (for now, just the count of languages other than English (LOTE))
|
| 108 |
+
- `fetch_200_lote, fetch_200_lote_pct`
|
| 109 |
+
- For a subset of the numbers, there is a `foo_pct` (eg `fetch3xx_pct`) which can help you avoid doing math in SQL. It is an integer 0-100.
|
| 110 |
+
- There are raw numbers from our crawler logs, which also reveal the crawl budget and if we exhausted it
|
| 111 |
+
- `nutch_fetched, nutch_gone, nutch_notModified, nutch_numRecords, nutch_redirPerm, nutch_redirTemp, nutch_unfetched`
|
| 112 |
+
- `nutch_fetched_pct, nutch_gone_pct, nutch_notModified_pct, nutch_redirPerm_pct, nutch_redirTemp_pct, nutch_unfetched_pct`
|
| 113 |
+
- There is a size summary (average and median size (compressed))
|
| 114 |
+
- `warc_record_length_median, warc_record_length_av` (will be renamed to _avg in v3)
|
| 115 |
+
|
| 116 |
+
The full schema is available here: [athena_schema.v2.sql](https://github.com/commoncrawl/cc-host-index).
|
| 117 |
+
|
| 118 |
+
## Known bugs
|
| 119 |
+
|
| 120 |
+
- Some of the partitions have a different schema from others, so you will get errors for some of the columns in some of
|
| 121 |
+
the crawls. We recommend that you avoid using those crawls, and only use the columns you need.
|
| 122 |
+
- When the S3 bucket is under heavy use, AWS Athena will sometimes throw 503 errors. We have yet to figure out how to increase the retry limit.
|
| 123 |
+
- Hint: https://status.commoncrawl.org/ has graphs of S3 performance for the last day, week, and month.
|
| 124 |
+
- The sort order is a bit messed up, so database queries take more time than they should.
|
| 125 |
+
|
| 126 |
+
## Expected changes in test v3
|
| 127 |
+
|
| 128 |
+
- `warc_record_length_av` will be renamed to `_avg` (that was a typo)
|
| 129 |
+
- more `_pct` columns
|
| 130 |
+
- count truncations: length, time, disconnect, unspecified
|
| 131 |
+
- addition of indegree and outdegree from the web graph
|
| 132 |
+
- improve language details to be more than only LOTE and LOTE\_pct
|
| 133 |
+
- `content_language_top`, `content_language_top_pct`
|
| 134 |
+
- add unicode block information, similar to languages
|
| 135 |
+
- `prank10` needs its power law touched up (`hcrank10` might change too)
|
| 136 |
+
- there's a sort problem that .com shards have a smattering of not-.com hosts. This hurts performance.
|
| 137 |
+
- add domain prank/hcrank
|
| 138 |
+
- CI running against S3
|
| 139 |
+
- `robots_digest_count_distinct`
|
| 140 |
+
- `robots_digest` (if there is exactly 1 robots digest)
|
| 141 |
+
- Summarize `fetch_redirect`: same surt, same surt host, other.
|
| 142 |
+
|
| 143 |
+
## Contributing
|
| 144 |
+
|
| 145 |
+
We'd love to get testing and code contributions! Here are some clues:
|
| 146 |
+
|
| 147 |
+
- We'd love to hear if you tried it out, and what your comments are
|
| 148 |
+
- We'd love to have python examples using Athena, similar to duckdb
|
| 149 |
+
- We'd love to have more python examples
|
| 150 |
+
- Please use pyarrow whenever possible
|
| 151 |
+
|
| 152 |
+
## Terms of Use
|
| 153 |
+
|
| 154 |
+
[https://commoncrawl.org/terms-of-use](https://commoncrawl.org/terms-of-use)
|