---
license: apache-2.0
language:
- en
- pt
base_model: DedeProGames/Kiyo-230M-Preview
library_name: transformers
pipeline_tag: text-generation
tags:
- kiyo
- llama
- sft
- instruct
- conversational
- small-language-model
- bilingual
datasets:
- HuggingFaceTB/smoltalk2
- HuggingFaceTB/smol-smoltalk
- HuggingFaceH4/ultrachat_200k
- allenai/Dolci-Instruct-SFT
buckets:
- DedeProGames/kiyo-230m-instruct-checkpoints
---

A compact English / Portuguese chat model, pre-trained from scratch and fine-tuned for conversation.
## 1. Introduction
We are introducing **Kiyo-230M-Instruct**, a compact **230M-parameter chat model** from the Kiyo family. It starts from **Kiyo-230M-Preview**, a decoder-only language model pre-trained from scratch, and goes through full supervised fine-tuning on about **165,000 English and Portuguese conversations**, so it can follow instructions, hold multi-turn conversations, and answer in clean Markdown.
Kiyo-230M-Instruct is made for people who enjoy small models: tinkerers, students, researchers, and anyone prototyping a lightweight assistant on modest hardware. It uses a modern Llama-style architecture (grouped-query attention, RoPE, SwiGLU, RMSNorm), a **2,048-token context window**, and a native ChatML-style chat template.
> **Scope, honestly.** At 230M parameters this is a *small* model: a fun and fast companion for demos, experiments, and light chat, not a stand-in for multi-billion-parameter assistants. The sections below show where it stands today next to other small models.
| | |
|---|---|
| 🧠 **Parameters** | 229.7M |
| 🏗️ **Architecture** | Llama-style decoder · 32 layers · GQA (12 query / 4 KV heads) |
| 📏 **Context** | 2,048 tokens |
| 🌍 **Languages** | English, Portuguese |
| 📦 **Weights** | BF16 safetensors · 459 MB |
| 📜 **License** | Apache-2.0 |
## 2. Highlights
- **Pre-trained from scratch, then fully fine-tuned.** The weights start at Kiyo-230M-Preview, which was trained from scratch (the tokenizer follows the SmolLM2 vocabulary).
- **Bilingual conversations.** The SFT data is about 70% English and 30% Portuguese by token count, and in our quick comparison it was the only one of the four models that answered in fluent Portuguese.
- **Compact.** 229.7M parameters: 459 MB in BF16, about 0.92 GB in FP32.
- **Competitive for its size class.** In our four-benchmark comparison it sits in the same tier as SmolLM2-135M-Instruct and BananaMind-2-Pro and far ahead of Supra2-100M-Instruct (see Benchmarks), while being the largest of the four.
- **Modern architecture.** 32 layers, grouped-query attention (12 query heads, 4 KV heads), RoPE, SwiGLU, RMSNorm, tied embeddings.
- **Native chat template with multi-turn support** (`<|im_start|>` / `<|im_end|>`).
- **Assistant-only loss.** 119M supervised assistant tokens, so training focuses on answering rather than echoing prompts.
- **Open recipe.** Hyperparameters, data counts, and the run summary ship with the weights (`training_summary.json`).
- **Easy to try.** A live chat demo is one click away in the Space.
## 3. 🧪 Benchmarks
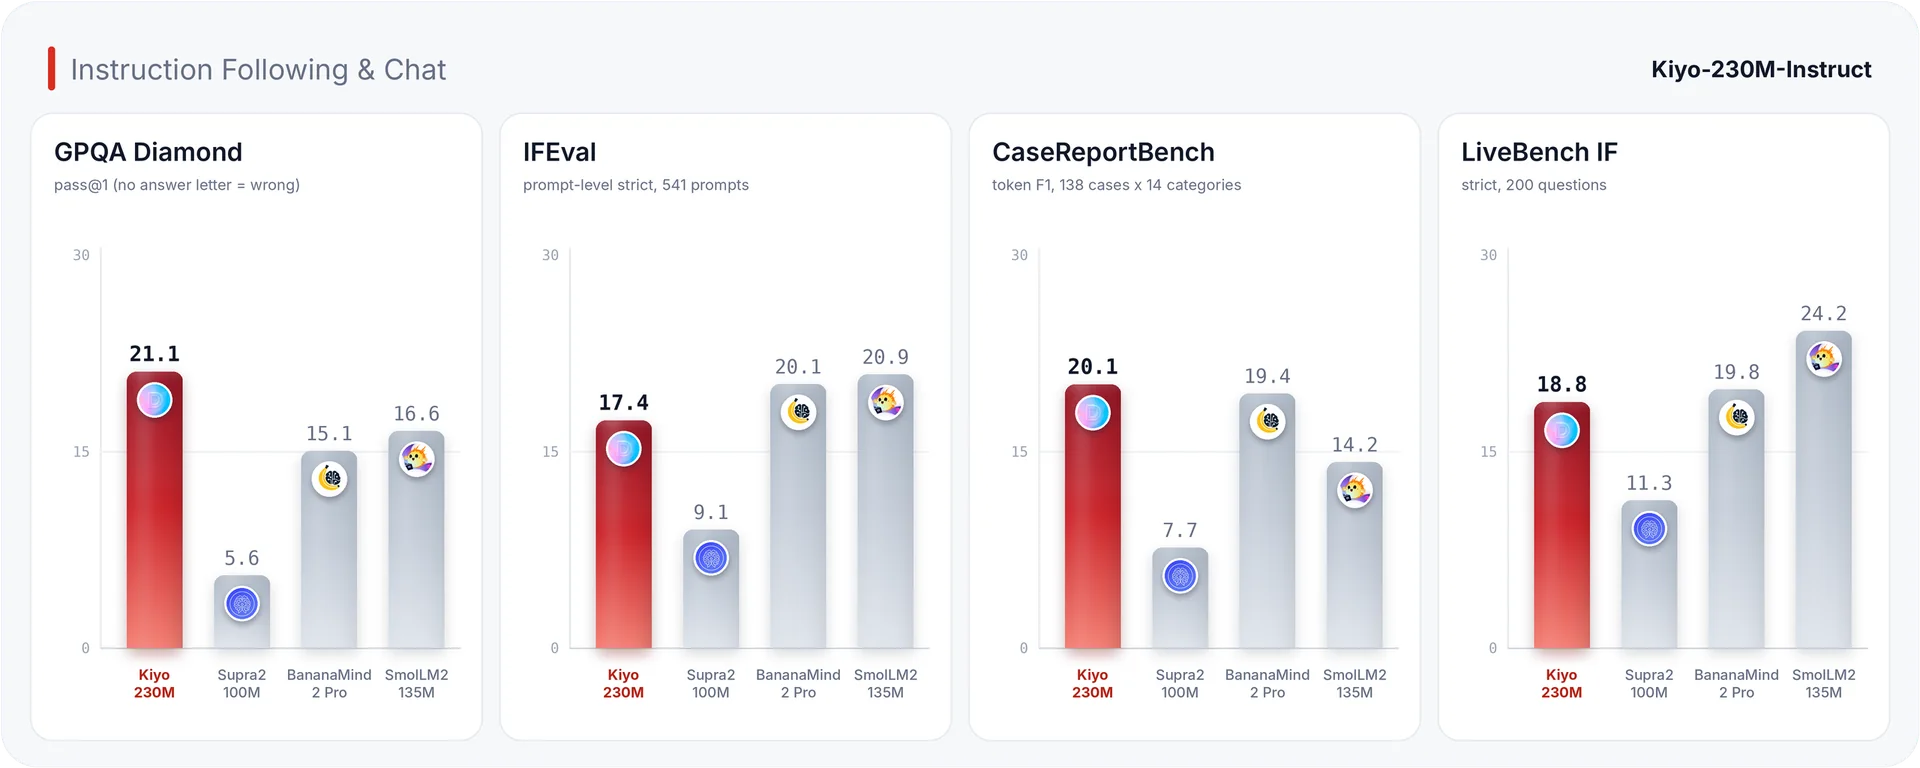
| Benchmark | Metric | **Kiyo-230M-Instruct** | Supra2-100M-Instruct | BananaMind-2-Pro-Preview-Chat | SmolLM2-135M-Instruct |
|---|---|---:|---:|---:|---:|
| *Parameters* | | *229.7M* | *100.7M* | *139.0M* | *134.5M* |
| GPQA Diamond | pass@1 (198 questions × 5 samples) | **21.11** | 5.56 | 15.05 | 16.57 |
| IFEval | prompt-level strict | 17.38 | 9.06 | 20.15 | **20.89** |
| CaseReportBench | token F1 | **20.11** | 7.68 | 19.44 | 14.20 |
| LiveBench Instruction Following | strict, 200 questions | 18.77 | 11.28 | 19.75 | **24.23** |
Bold marks the best score in each row. Kiyo-230M-Instruct is also the largest model in this comparison.
**How to read these numbers.** All four models ran under identical conditions, and the scores are small in absolute terms because these are small models. With a single run per benchmark, treat gaps of a point or two as ties.
- **Overall:** Kiyo-230M-Instruct, SmolLM2-135M-Instruct, and BananaMind-2-Pro are in the same tier, and all three are far ahead of Supra2-100M-Instruct.
- **CaseReportBench:** Kiyo and BananaMind are effectively tied (20.1 vs 19.4), ahead of SmolLM2 (14.2) and Supra2 (7.7).
- **IFEval and LiveBench Instruction Following:** SmolLM2-135M-Instruct and BananaMind-2-Pro score higher than Kiyo-230M-Instruct in this run.
- **GPQA Diamond:** a pass@1 counts an answer as wrong when no option letter can be extracted. Among the answers where a letter was found, every model sits close to the 25% chance level (Kiyo 25.3, Supra2 27.0, SmolLM2 23.4, BananaMind 26.1). This benchmark therefore mostly measures whether a small model replies in the requested format, not scientific knowledge.
Evaluation protocol
- **Same conditions for every model:** same prompts, same sampling (temperature 0.1, top-k 50, repetition penalty 1.05), each model's own chat template, no system prompt, FP16 on a single NVIDIA T4, prompts truncated to 1,536 tokens, up to 512 new tokens (IFEval 1,024, GPQA 384, CaseReportBench 192).
- **GPQA Diamond:** 198 questions, options shuffled deterministically, 5 samples per question at temperature 0.6, pass@1 over 990 attempts. Answers without a parseable option letter count as wrong.
- **IFEval:** 541 prompts, prompt-level strict accuracy with the lm-evaluation-harness checkers. The harness counts a language-detection failure as "followed", which can inflate models that emit unreadable text. In our logs this only affected Supra2-100M-Instruct (its exact inflation was not measured), and it ranks last either way.
- **LiveBench Instruction Following:** 200 questions from the current release, no LLM judge; the per-question score is the mean of "all instructions followed" and "fraction of instructions followed" (strict).
- **CaseReportBench:** clinical dense extraction, 138 case reports × 14 categories (1,932 prompts, 929 with gold spans). Score: token-level F1 on the pairs that have gold spans. The paper's token-set ratio is not used because it can reach 100 for degenerate answers. The 1,003 pairs without gold spans are not scored; Kiyo, BananaMind, and SmolLM2 almost never answer with an empty list for them (0.1% to 0.5%), so this benchmark rewards extraction, not knowing when to abstain.
- Single run, single seed: treat differences of a point or two as noise.
CaseReportBench: token F1 by category
| Category | Kiyo-230M-Instruct | Supra2-100M-Instruct | BananaMind-2-Pro-Preview-Chat | SmolLM2-135M-Instruct |
|---|---:|---:|---:|---:|
| History & chief complaint | 44.13 | 17.30 | 39.65 | 31.25 |
| Laboratory & imaging | 24.95 | 9.59 | 23.50 | 17.28 |
| Dermatological | 23.37 | 7.56 | 20.90 | 13.20 |
| Pregnancy | 21.07 | 6.47 | 22.81 | 19.63 |
| Neurological | 19.54 | 7.61 | 20.33 | 12.68 |
| Genitourinary | 13.63 | 6.57 | 16.41 | 9.71 |
| Eye, ear, nose & throat | 13.20 | 4.80 | 11.00 | 7.03 |
| Musculoskeletal | 11.70 | 4.34 | 10.87 | 9.07 |
| Endocrine | 11.22 | 3.85 | 13.37 | 8.75 |
| Vitals & hematology | 10.58 | 3.81 | 11.83 | 8.65 |
| Cardiovascular | 9.67 | 5.01 | 10.29 | 6.95 |
| Gastrointestinal | 8.01 | 3.70 | 8.28 | 7.73 |
| Respiratory | 7.98 | 1.18 | 8.25 | 5.03 |
| Lymphatic | 2.17 | 0.60 | 3.58 | 3.53 |
## 4. 💬 Example conversations
A few of the model's best responses, hand-picked from a 24-prompt test and left unedited (shortened only where marked with […]). They were generated with near-greedy sampling (temperature 0.1, top-k 50, repetition penalty 1.05) so that they are reproducible; for everyday chat we recommend temperature 0.7 and top-p 0.9, which gives more varied answers. The full picture is in the side-by-side results below.
**Follow a precise instruction**
> **You:** Explain what a language model is in two sentences.
>
> **Kiyo:** A language model is a computer program that uses natural language processing (NLP) to understand and generate human-like text, such as speech, text messages, or even written documents. It uses algorithms to analyze the context, meaning, and tone of the text to generate a coherent and accurate representation of the message.
**Change the tone**
> **You:** Rewrite this sentence in a more formal tone: 'hey, can u send me the report asap?'
>
> **Kiyo:** Certainly! Here’s a more formal version of your sentence:
>
> 'Could you please send me the report at your earliest convenience?'
**Speak Portuguese**
> **Você:** Me explique em poucas frases o que é inteligência artificial.
>
> **Kiyo:** A inteligência artificial é um campo da ciência que se concentra em desenvolver sistemas capazes de processar, interpretar e adaptar informações de maneira eficiente e sem a necessidade de especialistas humanos. Ela é fundamental para a tomada de decisões, a resolução de problemas complexos e a criação de produtos e serviços que atendam às necessidades do mercado. A inteligência artificial tem se tornado cada vez mais relevante e amplamente utilizada, permitindo que indivíduos e empresas se comuniquem de forma mais eficaz e eficiente.
> **Você:** Me ajuda a organizar meus estudos?
>
> **Kiyo:** Claro, posso ajudá-lo a organizar seus estudos! Aqui estão algumas dicas para te ajudar:
>
> 1. **Defina seu objetivo**: Antes de começar, é importante ter claro o que você deseja alcançar com seus estudos. Isso ajudará a guiar suas decisões e a manter a motivação.
> 2. **Escolha um local**: Escolha um espaço tranquilo e confortável para estudar. Considere a disponibilidade das instalações, a disponibilidade de equipamentos necessários e a disponibilidade de acomodações.
> 3. **Organize suas tarefas**: Organize suas tarefas diariamente. Isso inclui definir horários, prioridades e prazos. Use ferramentas de gerenciamento de tarefas para manter o controle do progresso.
>
> […]
### Side-by-side sanity test
The same 24 prompts (22 in English, 2 in Portuguese) were sent to all four models with identical settings. The checks are simple and automatic (format and key facts), so this is a quick sanity test, not a benchmark: single run, near-greedy sampling, FP16 on a T4.
| Model | English checks (of 16) | Portuguese checks (of 2) | Average answer length (tokens) | Answers that hit the 256-token limit (of 24) | Repetition |
|---|---:|---:|---:|---:|---:|
| **Kiyo-230M-Instruct** | 6 | **2** | 101 | 3 | 0.07 |
| Supra2-100M-Instruct | 5 | 0 | 256 | 24 | 0.55 |
| SmolLM2-135M-Instruct | **10** | 0 | 104 | 4 | **0.03** |
| BananaMind-2-Pro-Preview-Chat | 6 | 0 | 125 | 3 | 0.10 |
*Repetition = share of repeated word trigrams in the answers (0 means no repetition).*
- **English:** SmolLM2-135M-Instruct passed the most checks (10 of 16). Kiyo-230M-Instruct and BananaMind-2-Pro passed 6, and Supra2-100M-Instruct passed 5 while repeating itself until the token limit in every answer.
- **Portuguese:** Kiyo-230M-Instruct was the only model that answered in fluent Portuguese (2 of 2). The other models answered in English, mixed languages, or repeated the prompt.
- **At this size, everyone struggles** with arithmetic and with strict format instructions such as all-caps answers or an exact closing phrase.
What the 18 checks look at
| Prompt | Check |
|---|---|
| Capital of France | mentions Paris |
| Author of Romeo and Juliet | mentions Shakespeare |
| Chemical symbol of gold | contains "Au" |
| 17 + 25 | contains 42 |
| Train: 60 km in 45 minutes | contains 80 |
| Three sleep tips as a bullet list | exactly 3 list items |
| Python Fibonacci function | code parses and defines a Fibonacci function |
| "Is the Earth flat? Reply with only yes or no." | the answer is only "no" |
| Five fruits, lowercase, comma-separated | exactly that format, no other text |
| Polite email asking for Friday off | mentions Friday, at least 25 words |
| Photosynthesis for a 10-year-old | exactly 3 sentences, mentions plants and sun/light |
| Five coffee-shop names | at least 5 list items |
| Ideal weekend in at most 30 words | 30 words or fewer |
| JSON object with name and age | valid JSON with both keys |
| Study tip ending with "Hope this helps!" | ends with that exact phrase |
| One sentence about the moon in capitals | all capitals |
| Two Portuguese prompts | real Portuguese, not a loop, not English/French/Spanish |
Six more prompts (greeting, language model, poem, study plan, formal rewrite, summary) are read by eye and not scored.
## 5. 🖥️ CPU evaluation
Small models are meant to run anywhere, so we also measured how they behave on a plain CPU, with no GPU involved.
| Model | Params | Decode, 1 stream (tokens/s) | Decode, batch of 8 (tokens/s) | Prefill (tokens/s) | Peak RAM (FP32) |
|---|---:|---:|---:|---:|---:|
| **Kiyo-230M-Instruct** | 229.7M | 13.1 | 55.1 | 339 | 1.44 GB |
| Supra2-100M-Instruct | 100.7M | 27.4 | 121.8 | 989 | 0.93 GB |
| SmolLM2-135M-Instruct | 134.5M | 19.7 | 82.5 | 534 | 1.12 GB |
| BananaMind-2-Pro-Preview-Chat | 139.0M | 16.0 | 53.6 | 465 | 1.04 GB |
> Measured on 4 vCPUs (Intel Xeon @ 2.8 GHz, AVX-512 VNNI), PyTorch CPU with Transformers 5.19, FP32, 4 threads. Decode = 128 new tokens after a 64-token prompt; prefill = one 512-token prompt; median of 2 to 3 runs. Kiyo's row was measured on an architecture-identical model with random weights, because decoding speed does not depend on the weight values.
Kiyo-230M-Instruct is the largest model in this comparison, so it is also the slowest per token on CPU: about 13 tokens/s for a single stream here, or roughly 20 seconds for a 256-token answer.
## 6. ⚡ Quickstart
```bash
pip install -U "transformers>=5" torch
```
```python
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
repo = "DedeProGames/Kiyo-230M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(repo)
model = AutoModelForCausalLM.from_pretrained(repo, dtype=torch.float32) # FP32 is the fastest option on most CPUs; use bfloat16 on GPU
chat = [{"role": "user", "content": "Can you help me organize my study plan?"}]
inputs = tokenizer.apply_chat_template(chat, add_generation_prompt=True, return_tensors="pt", return_dict=True)
output = model.generate(
**inputs,
max_new_tokens=256,
do_sample=True,
temperature=0.7,
top_p=0.9,
repetition_penalty=1.05,
eos_token_id=2, # <|im_end|>
pad_token_id=0, # <|endoftext|>
)
print(tokenizer.decode(output[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True))
```
**Multi-turn chat.** Keep the conversation history in the prompt and make sure prompt + answer stay within 2,048 tokens:
```python
chat = [
{"role": "user", "content": "Me ajuda a organizar meus estudos?"},
{"role": "assistant", "content": "Claro! Quais matérias você quer estudar e quanto tempo tem por dia?"},
{"role": "user", "content": "Matemática e inglês, cerca de 2 horas por dia."},
]
inputs = tokenizer.apply_chat_template(chat, add_generation_prompt=True, return_tensors="pt", return_dict=True)
```
**Prompt format** (produced automatically by the chat template):
```text
<|im_start|>user
Hello!<|im_end|>
<|im_start|>assistant
```
| Setting | Recommended value |
|---|---|
| `temperature` | 0.7 |
| `top_p` | 0.9 |
| `repetition_penalty` | 1.05 |
| `max_new_tokens` | 256 |
## 7. 🧱 Model details
| Field | Value |
|---|---:|
| Parameters | 229.7M |
| Architecture | Llama-style decoder (`LlamaForCausalLM`) |
| Layers | 32 |
| Hidden size | 768 |
| Intermediate size | 1,920 |
| Attention heads / KV heads | 12 / 4 (grouped-query attention) |
| Head dimension | 64 |
| Activation | SwiGLU |
| Normalization | RMSNorm |
| Positional encoding | RoPE (θ = 10,000) |
| Vocabulary | 49,152 (GPT-2 style BPE) |
| Context length | 2,048 |
| Embeddings | Tied input/output |
| Special tokens | `<\|im_start\|>`, `<\|im_end\|>` (EOS, id 2), `<\|endoftext\|>` (PAD, id 0) |
| Weight format | BF16 safetensors (459 MB) |
## 8. 📚 Training
**Base model.** [Kiyo-230M-Preview](https://huggingface.co/DedeProGames/Kiyo-230M-Preview), an intermediate checkpoint of a from-scratch pre-training run (revision `d9e0930`). See its card for the pre-training data and token budget.
**Supervised fine-tuning** (run `sft-20261013-v1`):
| Field | Value |
|---|---:|
| Prepared data | 165,735 conversations · 149.4M tokens · 119.2M supervised (assistant) tokens |
| Multi-turn share | 73.8M of the 149.4M tokens |
| Language mix (tokens) | English 104.4M (70%) · Portuguese 45.0M (30%) |
| Epochs / steps | 2 epochs · 10,360 steps |
| Effective batch size | 32 (8 × 4 gradient accumulation) |
| Learning rate | 1e-4, anchored cosine schedule |
| Precision | BF16 activations, FP32 master weights |
| Context | 2,048 tokens |
| Training time | about 4.2 hours |
| Held-out assistant-token loss | 1.292 (training loss 1.260) |
| Software | PyTorch 2.10.0, Transformers 5.19.0, TRL 1.15.0 |
The weights are exported as BF16 safetensors. Complete optimizer, scheduler, and RNG training checkpoints are kept in a private bucket (`DedeProGames/kiyo-230m-instruct-checkpoints`).
Data mixture (share of sequence tokens)
| Source | Share |
|---|---:|
| Portuguese conversations | 30.1% |
| SmolTalk2 · chat | 29.5% |
| UltraChat 200k | 15.1% |
| smol-smoltalk (core) | 11.0% |
| Dolci-Instruct-SFT | 10.0% |
| SmolTalk2 · rewrite | 4.0% |
| SmolTalk2 · everyday | 0.2% |
## 9. ⚠️ Intended use and limitations
**Good for:** demos, teaching, research on small language models, fine-tuning experiments, and lightweight English / Portuguese chat prototypes.
**Keep in mind:**
- It is a small model. Expect factual mistakes, invented details, arithmetic errors, weak multi-step reasoning, repetition in open-ended text such as poems, and a tendency to agree with false premises. Treat answers as drafts to verify. The benchmark scores above are low in absolute terms.
- The context window is 2,048 tokens, shared between your prompt and the answer.
- English and Portuguese are the target languages; other languages are not supported.
- It was fine-tuned from an intermediate pre-training checkpoint, not a fully trained one.
- It inherits the biases and gaps of its pre-training and fine-tuning data. No dedicated safety evaluation is documented, so do not use it for medical, legal, financial, or other high-stakes decisions.
## 10. 📜 Data attribution
- **SmolTalk2** and **smol-smoltalk**: HuggingFaceTB, preserving contributing source terms.
- **UltraChat 200k**: HuggingFaceH4, MIT.
- **Dolci-Instruct-SFT**: AllenAI, ODC-BY collection plus contributing source terms.
The mixture uses only existing public teacher responses. No benchmark transcripts were used for SFT.
## 11. Citation
```bibtex
@misc{kiyo230minstruct2026,
title = {Kiyo-230M-Instruct: a compact English/Portuguese chat model trained from scratch},
author = {DedeProGames},
year = {2026},
howpublished = {\url{https://huggingface.co/DedeProGames/Kiyo-230M-Instruct}}
}
```
## 12. Acknowledgements
Thanks to HuggingFaceTB (the SmolLM2 architecture family and vocabulary, and the SmolTalk data), HuggingFaceH4 (UltraChat), and AllenAI (Dolci). Benchmarks were run with the lm-evaluation-harness IFEval checkers, GPQA, LiveBench, and CaseReportBench.
Made with ❤️ by DedeProGames